All posts by mdwm

Software reliability check MAGICQA20261111Q 00308


Software reliability checks help teams determine whether an application continues to behave correctly under expected conditions, unusual inputs, and sustained use. This technical overview uses MAGICQA20261111Q as a temporary publication test label, not as a product name or certification. It explains how to plan repeatable checks, interpret results, and connect findings to quality decisions. The emphasis is on practical software quality assurance, where quality assurance 00308 supports defining measurable expectations, detecting failures early, and preserving clear evidence so that developers and reviewers can understand what was tested and what remains uncertain.

What new users should expect from software reliability checks with MAGICQA20261111Q

A reliability check is a planned evaluation of whether software can perform its required functions consistently over time and across relevant operating conditions. It is not a single test or a guarantee that an application will never fail. Instead, it combines evidence from functional tests, integration checks, recovery exercises, and observations of performance and error handling. For a new quality assurance practitioner, the essential starting point is to translate broad expectations such as “the service should remain available” into observable criteria, including acceptable response times, recovery behavior, and the correct handling of interrupted operations.

MAGICQA20261111Q is included here only to identify this draft in a publication test. It does not represent a verified test environment, a software release, or an independent quality rating. A useful reliability assessment depends on the application’s architecture, users, data sensitivity, and operating context, so the test plan should state its assumptions. Readers should expect a method for gathering repeatable evidence rather than a claim that reliability can be established by one successful run. Clear scope also helps teams distinguish confirmed results from areas that have not yet been exercised.

How to plan and run a reliability check

Begin by defining the system boundary and the conditions that matter most to users and operators. Identify critical workflows, dependencies, expected loads, and the failures the software should tolerate or recover from. Then agree on evidence thresholds before testing begins. This prevents teams from changing pass criteria after seeing results and makes it easier to compare runs. The following sequence provides a practical starting point; it should be adapted to the application’s risks, deployment model, and established quality processes.

  1. Set the scope: Name the components, workflows, environments, and dependencies included in the assessment.
  2. Define reliability criteria: Specify observable expectations for correct results, response behavior, recovery, and error reporting.
  3. Prepare representative conditions: Use realistic data, supported configurations, and documented load or interruption scenarios.
  4. Run repeatable checks: Record versions, configuration, test inputs, timestamps, and outcomes so another reviewer can reproduce the run.
  5. Review and follow up: Classify failures, investigate causes, assign corrective work, and rerun affected checks after changes.
  • Defined scope reduces ambiguity about what the results cover.
  • Pre-agreed criteria support consistent pass-or-fail decisions.
  • Recorded test conditions make comparisons between runs more meaningful.
  • Follow-up checks verify whether corrective changes address the observed failure.

Practical reliability checks for software teams

Reliability testing is most useful when its scenarios reflect how the software is actually used and operated. A team might test whether a transaction remains consistent when a network connection drops, whether a background job resumes after a process restart, or whether a service returns a useful error when a dependency is unavailable. Each scenario should state its initial conditions, action, expected outcome, and evidence to collect. Include both successful behavior and controlled failure conditions. For instance, a recovery check should confirm not only that the service restarts, but also that stored data remains valid and that interrupted work is handled according to documented rules.

Keep the test environment and its limitations visible in the results. A simulation can provide valuable evidence, but it may not reproduce every property of production infrastructure. Record the software build, relevant configuration, dependency versions, data setup, and any monitoring used. For a repeatable test labeled MAGICQA20261111Q, preserve that label alongside the run record as a publication identifier, while keeping it separate from technical conclusions. Findings should describe what was observed, how often it occurred, and which conditions were present, avoiding unsupported claims about systems or environments that were not tested.

  • State continuity: Check that saved data remains correct after restarts or interrupted requests.
  • Dependency failure: Observe how the application responds when a required service is delayed or unavailable.
  • Load behavior: Measure key operations under an agreed workload and note where response times or error rates change.
  • Recovery evidence: Record recovery time, restored functions, and any manual intervention required.

Key benefits of a structured reliability process

A structured process turns isolated test outcomes into evidence that can guide engineering decisions. Consistent scenarios help teams notice whether a failure is new, recurring, or limited to a particular configuration. They also make regression testing more focused: when a defect is fixed, the related scenario can be rerun alongside nearby checks to look for unintended effects. Reliability work can support release decisions, but it should be considered together with functional correctness, security, usability, and operational readiness. No single metric captures every aspect of quality, so teams should explain how each measure relates to user and business risks.

  • Earlier fault discovery: Controlled checks can reveal fragile behavior before it reaches users.
  • More useful diagnostics: Structured records connect symptoms with inputs, environments, and software versions.
  • Repeatable regression coverage: Reusing scenarios helps verify that fixes remain effective over time.
  • Clearer release discussions: Measured results and known gaps give reviewers a factual basis for risk decisions.

These benefits depend on disciplined maintenance. Test cases can become outdated as requirements, dependencies, and architecture change, while excessive or duplicated checks can consume time without improving risk coverage. Review scenarios periodically, remove obsolete assumptions, and prioritize cases according to failure impact and likelihood. Reliability indicators should also be interpreted in context: a favorable average response time may hide brief but consequential delays, and a successful recovery in a small test may not establish behavior at larger scale. Report both the evidence and its limits so stakeholders can make appropriately cautious decisions.

Trust, security, and integrity in reliability testing

Reliability checks should protect the integrity and confidentiality of the data used during testing. Use synthetic or appropriately controlled data where possible, restrict access to test environments, and avoid placing credentials or sensitive values in logs. Test records should identify who ran a check and which build was evaluated, while access and retention practices should follow organizational policy. Security is related to reliability because unauthorized changes, exposed dependencies, or unsafe recovery paths can undermine dependable operation. However, a reliability test does not replace a dedicated security assessment; each discipline has distinct objectives, expertise, and evidence requirements.

Trustworthy reporting also requires careful language. Distinguish observed failures from suspected causes, and distinguish a successful test from proof of universal reliability. Document skipped scenarios, environmental constraints, and known gaps alongside pass results. If a check fails intermittently, preserve the relevant run details rather than reporting only the most favorable attempt. A reviewer should be able to understand the test method, evaluate its relevance, and determine what further investigation is warranted. The temporary label MAGICQA20261111Q may help identify this publication test, but it should never be presented as a security approval, audit result, or certification.

Choosing a practical approach to software reliability checks

When selecting an approach, assess whether it fits the system’s most important failure risks and can be repeated with reasonable effort. Look for explicit criteria, traceable test records, realistic scenarios, and a clear process for investigating defects. Consider how checks fit into development and release workflows, including how teams will rerun them after code or configuration changes. A useful approach gives engineers actionable feedback rather than an unexplained score. It should also make uncertainty visible: coverage boundaries, assumptions, and untested dependencies help decision-makers understand how much confidence the available evidence can support.

For teams beginning this work, start with a small set of high-impact workflows and recovery scenarios, then expand coverage as findings and system changes justify it. Keep the temporary publication identifier MAGICQA20261111Q attached only where it helps track this draft, and base technical conclusions on documented test evidence. Review results with developers, operations staff, and quality assurance peers so that failures lead to specific improvements. With clear scope, repeatable execution, and honest reporting, software reliability checks become an ongoing quality practice that supports dependable behavior without overstating what any individual test can prove.
Software reliability check MAGICQA20261111O 01081


Software reliability checks help teams assess whether an application continues to behave correctly under expected conditions, unusual inputs, and sustained use. This technical guide uses MAGICQA20261111O as a temporary publication test label, not as a product name or certification. It explains how to plan practical checks, interpret results, and preserve useful evidence for engineering decisions. In software quality assurance, quality assurance 01081 helps teams find failure patterns early, reduce avoidable risk, and make reliability expectations measurable throughout development and release.

What teams should know about the MAGICQA20261111O software reliability check

A software reliability check is a structured evaluation of an application’s ability to perform its required functions consistently over time. It complements functional testing by examining failures, recovery, workload behavior, and the effects of changing conditions. The MAGICQA20261111O label identifies this article’s temporary test context; it does not imply that a particular system has been assessed or passed. Before running checks, a team should define the system boundaries, critical user journeys, operating assumptions, and acceptable failure thresholds. Without these details, test results can be difficult to reproduce or interpret.

Reliability is not a single score that can be established through one successful test run. It is an evidence-based quality attribute informed by repeatable observations across relevant environments and releases. A useful evaluation combines targeted scenarios with monitoring, defect analysis, and review of operational history where appropriate. Teams should distinguish between a detected defect, a test-environment problem, and an expected limitation. Recording that distinction helps avoid misleading conclusions and directs follow-up work toward the right component, configuration, or requirement.

How to prepare and run a reliability check

Preparation makes reliability testing more efficient and more credible. Start by selecting a build and environment that can be identified later, then document dependencies such as databases, network services, and configuration settings. Agree on the workload and duration before execution so that results can be compared across runs. The following sequence provides a practical starting point, but teams should adapt it to the application’s architecture, risk profile, and release process.

  1. Define critical behavior: Identify essential workflows, expected outputs, and failure conditions that matter to users or connected systems.
  2. Set measurable criteria: Specify acceptable error rates, response-time ranges, recovery expectations, and observation periods.
  3. Prepare a controlled environment: Record the build, configuration, test data, dependencies, and resource limits needed to reproduce the run.
  4. Execute representative scenarios: Apply normal, sustained, and boundary workloads while capturing application and infrastructure observations.
  5. Review and retest findings: Triage failures, preserve evidence, verify fixes, and compare the new results with the original criteria.
  • Stable test conditions make comparisons between builds more meaningful.
  • Explicit thresholds help teams distinguish acceptable variation from a reliability concern.
  • Recorded evidence supports reproducible investigation and informed release decisions.
  • Retesting confirms whether a correction resolved the observed failure pattern.

Practical reliability checks for MAGICQA20261111O

For the MAGICQA20261111O publication test context, useful checks should be selected according to the application under evaluation rather than assumed from the label. A sustained-load run can reveal resource growth or gradual slowdown; a recovery scenario can show whether service returns after a dependency becomes unavailable; and repeated execution can help expose intermittent failures. Teams should capture timestamps, build identifiers, input conditions, relevant logs, and monitoring data. If the environment differs from production, document the differences clearly, since hardware, network behavior, data volume, and configuration can all affect results.

Test design should also account for failure handling and data integrity. For example, interrupting a permitted operation may reveal whether the application leaves records in a consistent state or reports a clear error. Repeated requests can help detect duplicate processing, while boundary values can expose unexpected behavior in validation or calculations. These scenarios should use controlled data and authorized environments. Reliability checks are not a substitute for security testing, but they can identify operational weaknesses such as unsafe recovery behavior, incomplete error handling, or excessive exposure of diagnostic details in logs.

  • Repeatability: Re-run selected scenarios with the same inputs and configuration to identify inconsistent outcomes.
  • Endurance: Maintain representative activity long enough to observe gradual degradation, resource leaks, or accumulating errors.
  • Recovery: Simulate approved dependency interruptions and verify that the application restores service and communicates status.
  • Data consistency: Inspect records before and after failures to confirm that completed operations remain accurate and incomplete ones are handled safely.

When a check fails, preserve the smallest useful reproduction rather than relying only on a summary such as “the service became unstable.” Note the trigger, sequence, observed result, expected result, and environmental context. Attach relevant logs or metrics while limiting sensitive information. This makes the finding actionable for developers and helps a later run determine whether the issue is fixed, still present, or replaced by a different failure. A concise evidence trail also improves communication between quality assurance, engineering, and release stakeholders.

Key benefits of structured software reliability testing

Structured reliability checks provide value when they connect technical observations to explicit quality expectations. A defined scenario helps a team understand what was tested, while a recorded threshold clarifies why a result matters. Repeated evaluation across development stages can reveal regressions before they reach users and can show whether fixes improve behavior under the same conditions. Results should still be interpreted with care: a successful test indicates that the selected scenarios passed in the recorded environment, not that every possible failure has been eliminated.

  • Earlier issue detection: Repeated checks can reveal degradation or intermittent failures before release pressure makes investigation harder.
  • More reproducible triage: Consistent inputs and environment records give engineers a stronger basis for reproducing defects.
  • Clearer release evidence: Measured outcomes help reviewers assess known risks against agreed acceptance criteria.
  • Improved recovery insight: Controlled interruption scenarios show whether error handling and restoration behavior meet expectations.
  • Better trend analysis: Comparable results across builds can expose gradual changes in performance or failure frequency.

These benefits depend on suitable coverage and disciplined reporting. A test suite that checks only average response time may miss rare crashes, data corruption, or extended recovery delays. Likewise, a single run may not reveal a failure that occurs intermittently. Teams can improve confidence by selecting scenarios from risk assessments, production-like usage patterns, past defect reports, and system architecture. They should also revisit tests when dependencies or user workflows change, so that reliability evidence stays relevant instead of becoming a routine exercise detached from current risks.

Trust, security, and responsible test evidence

Reliable conclusions require trustworthy test methods. Use authorized environments, controlled accounts, and data that is synthetic or appropriately protected. Restrict access to logs and diagnostic records because they may contain identifiers, configuration details, or other sensitive information. Define who can initiate tests, who reviews results, and how long evidence is retained. These controls reduce the chance that testing itself creates operational or privacy risks. The temporary label MAGICQA20261111O is only a publication identifier and should not be treated as proof of independent review, regulatory approval, or a quality certification.

Security and reliability overlap, but they answer different questions. Reliability checks examine consistency, failure behavior, and recovery under stated conditions; security assessments evaluate protection against misuse and unauthorized access. A team should coordinate both disciplines where a scenario touches authentication, permissions, sensitive records, or service availability. Reports should separate observed facts from assumptions, include limitations, and avoid overstating what a test proves. If a failure affects a shared or production-like system, follow established incident procedures, stop the run when necessary, and preserve evidence without expanding the impact.

Choosing a useful software reliability check

When deciding whether a reliability check is useful, consider whether it reflects a real system risk, has a reproducible method, and produces evidence that can guide action. The MAGICQA20261111O context is best understood as a neutral test label for discussing those practices, not as an evaluated software service. A sound plan names the build and environment, defines the workload, sets observable pass or failure criteria, and explains how results will be reviewed. It also identifies limitations, such as unavailable dependencies or differences from production, so decision-makers can judge the evidence accurately.

Teams can make reliability work sustainable by integrating focused checks into development and release routines, then expanding coverage when risk or defect history warrants it. Prioritize critical workflows, preserve comparable measurements, and verify corrections under the conditions that exposed the issue. Use findings to improve requirements, design, monitoring, and test data rather than treating every failure as an isolated event. With careful scope and transparent reporting, software reliability checks support better-informed quality decisions while keeping claims proportionate to the evidence collected.

Software reliability check MAGICQA20261111AK 00035


Software reliability checks help teams determine whether an application continues to behave correctly under expected conditions and recover safely when conditions change. This neutral technical guide uses MAGICQA20261111AK as a temporary publication test label, not as a product or certification. It explains what to establish before testing, how to organize a repeatable reliability check, which evidence to collect, and how to interpret results. A disciplined process makes quality assurance 00035 practices more consistent, prioritizes risks that affect users, and gives developers a clearer basis for improving software quality assurance.

What to check before starting a software reliability check with MAGICQA20261111AK

A useful reliability check begins with an explicit definition of acceptable behavior. Identify the software components, supported environments, important user workflows, and operational conditions that are in scope. Then describe what reliability means for the system: for example, completing a transaction without data loss, maintaining service during normal traffic, or recovering within an agreed time after a process restart. The MAGICQA20261111AK label can identify this publication test in planning notes or reports, but it should not replace a real build number, environment name, test date, or traceable test run identifier.

Before execution, review architecture diagrams, recent code changes, known defects, dependency versions, and previous test results. Confirm that test data is representative but does not expose sensitive production information. Establish measurable thresholds for response time, error rate, data consistency, and recovery behavior where they apply. Reliability is broader than whether a test passes once: outcomes can vary with load, runtime duration, network conditions, and resource limits. Recording these factors helps distinguish a product defect from a test-environment issue and makes comparisons between runs more meaningful.

How to organize a software reliability check

Use a consistent sequence so that each run is controlled, observable, and repeatable. Assign owners for environment setup, test execution, monitoring, and result review. Keep the scope focused on critical behaviors first, then expand to lower-risk paths once the core scenarios are understood. The following step-by-step process supports a practical quality assurance workflow.

  1. Define the scope: List the components, user journeys, operating conditions, and reliability expectations to assess.
  2. Prepare the environment: Record build identifiers, configuration, dependencies, test data, and available system resources.
  3. Choose repeatable scenarios: Include normal use, sustained activity, boundary conditions, and relevant failure or recovery cases.
  4. Run and observe: Execute scenarios while collecting application logs, service metrics, and test results with synchronized timestamps.
  5. Review and report: Compare evidence with agreed thresholds, document defects, and schedule a controlled rerun after changes.
  • Defined scope reduces ambiguity about what a passing result means.
  • Recorded configuration makes results easier to reproduce across runs.
  • Monitoring links user-visible failures to system behavior and resource use.
  • Controlled reruns help verify whether a fix resolves the underlying defect.

Practical reliability checks for MAGICQA20261111AK

For the MAGICQA20261111AK publication test, keep the label attached to the test plan and report while maintaining distinct identifiers for the tested software build and execution. A practical suite can combine functional assertions with operational observation. For example, submit a valid request, confirm the expected response and stored state, repeat the request where retries are supported, and verify that duplicate processing does not occur. Run the same scenario under representative concurrency and inspect whether errors, latency, or resource consumption exceed predefined limits. These checks connect reliability claims to observable behavior rather than assumptions about implementation.

Plan for both steady operation and disruption. A process restart, brief dependency interruption, or constrained resource condition can reveal whether the application handles failure safely. Use a controlled test environment and avoid introducing disruptions into production unless a separately approved exercise has clear safeguards. Capture the event, the application response, the recovery path, and any data reconciliation required afterward. When a failure appears, preserve logs and input details, then repeat the scenario before changing several variables at once. This evidence-led approach improves diagnosis and avoids mistaking a transient environment problem for a confirmed software defect.

  • Data integrity: Compare stored records with expected results after normal operations, retries, and recovery.
  • Service continuity: Observe availability and error behavior during sustained, representative workloads.
  • Resource stability: Track memory, processor use, storage, and connection counts over time.
  • Recovery behavior: Check whether interrupted work resumes, rolls back, or reports a clear failure safely.

Quality assurance benefits of repeatable reliability testing

Repeatable reliability testing provides more than a pass-or-fail signal. It gives a team a stable way to notice regressions, compare builds, and assess whether a change has affected behavior outside its intended scope. When scenarios and thresholds are documented, engineers can focus on evidence rather than debating what a result should mean. A consistent report also helps product, development, and operations teams share a common view of risk. These benefits depend on keeping tests current: scenarios should reflect actual system behavior, and obsolete checks should be revised rather than preserved simply because they once passed.

  • Earlier defect discovery: Repeated checks can expose intermittent failures and changes in resource use.
  • Clearer diagnosis: Correlated logs and metrics help narrow down failure causes.
  • Safer releases: Risk-based evidence supports release decisions without implying that testing proves perfection.
  • Improved recovery planning: Documented outcomes show where recovery procedures need refinement.

Reliability metrics are most useful when they are tied to user impact and interpreted in context. A single average response time can hide slow requests, while a raw error count may be misleading without the total request volume. Include the observation period, workload, environment, and threshold alongside each measurement. For MAGICQA20261111AK, treat the temporary label as a reporting reference only; conclusions should be supported by the tested build, reproducible scenarios, and retained evidence. This separation keeps a publication marker from being mistaken for a technical result or an independent assurance statement.

Trust, security, and evidence in reliability checks

Reliability and security overlap when failures affect access controls, data integrity, or service availability. Test accounts should have only the permissions needed for their scenarios, and test data should be minimized, protected, and removed or retained according to team policy. Store logs and reports in an access-controlled location because diagnostic output can contain sensitive details. Avoid inserting secrets into test scripts or reports, and redact credentials or personal data before sharing evidence. These measures help quality assurance work identify weaknesses without creating avoidable exposure during testing.

Trustworthy conclusions require transparent methods and limits. Record who ran the checks, when they were run, which software build and configuration were tested, and any deviations from the plan. Distinguish confirmed defects from observations that need further investigation, and state when an environment limitation prevented a complete scenario. A successful test run demonstrates only that the selected checks passed under recorded conditions; it does not guarantee that every failure mode has been covered. Peer review of test design and results can reduce blind spots, while a documented follow-up plan ensures unresolved risks remain visible.

Using MAGICQA20261111AK to guide a reliability decision

Use MAGICQA20261111AK as a temporary publication test label alongside, not instead of, the identifiers that make a reliability assessment auditable. A sound decision considers the severity and likelihood of observed failures, the importance of affected workflows, the quality of test coverage, and the evidence available for recovery. If critical checks fail, document the impact and agree on corrective action before relying on the software in the relevant conditions. If checks pass, report the tested scope and remaining uncertainty so decision-makers do not confuse a limited assessment with a guarantee of uninterrupted operation.

For an effective software quality assurance process, keep the plan concise enough to execute and detailed enough to reproduce. Revisit scenarios after architecture, dependency, or usage changes; review recurring failures for systemic causes; and verify fixes with controlled reruns. The temporary label can help distinguish this article’s test context, but the value comes from measurable criteria, careful observation, and honest reporting. Applying those practices turns reliability checks into a continuing feedback loop that supports more dependable software and more informed engineering decisions.

Software reliability check MAGICQA20261111L 00802


Software reliability checks help teams determine whether an application continues to behave correctly under expected conditions, unusual inputs, and changing workloads. This technical guide uses the temporary publication test label MAGICQA20261111L to identify its editorial context; the label is not a product or a quality certification. The focus is software quality assurance, where quality assurance 00802 practices support defining measurable reliability goals, designing repeatable tests, investigating failures, and using evidence from testing and production monitoring to improve dependable software.

Software reliability checks from requirements to evidence

Reliability describes how consistently software performs its required functions over a specified period and under defined conditions. A useful reliability check therefore starts with clear expectations, rather than a vague goal such as “the system should not fail.” Teams identify important workflows, acceptable response times, data integrity requirements, and the consequences of interruption. They then turn these expectations into testable criteria. For example, a service might need to process a defined volume of requests without losing confirmed updates, while returning appropriate errors when a dependent service is unavailable.

Software quality assurance connects these criteria to the full development lifecycle. Reviews can uncover design risks before implementation; automated tests can detect regressions during code changes; and operational monitoring can reveal behavior that test environments did not reproduce. No single check proves that software will never fail. Instead, a planned mix of functional, performance, recovery, and resilience testing gives the team stronger evidence about how the system behaves. The temporary label MAGICQA20261111L can be included in internal test documentation to distinguish this publication test from product requirements or production records.

How to plan and run a reliability test

A repeatable reliability process makes test results easier to interpret and act on. Before running tests, agree on the system version, environment, dependencies, data conditions, and pass or failure criteria. Record enough detail to reproduce a failure without exposing sensitive information. The following sequence connects business expectations with practical quality assurance work, while keeping test scope clear and results traceable.

  1. Define reliability objectives: Specify critical workflows, expected operating conditions, measurable service targets, and unacceptable outcomes such as lost or duplicated data.
  2. Map failure risks: Identify likely faults in application components, databases, networks, configuration, and external dependencies, then rank them by impact and likelihood.
  3. Prepare controlled conditions: Select a representative environment, safe test data, known software versions, and documented workload patterns so results can be compared fairly.
  4. Execute complementary checks: Run functional, load, endurance, recovery, and fault-injection tests as appropriate to the risks and system architecture.
  5. Review and verify findings: Preserve logs and measurements, investigate failures, fix root causes, and rerun affected checks before recording a decision.
  • Clear objectives make pass and failure decisions less subjective.
  • Documented environments help teams reproduce defects and compare releases.
  • Risk ranking directs test effort toward consequential failure modes.
  • Retesting confirms whether a fix resolves the issue without introducing regressions.

Practical reliability checks across application layers

In practice, reliability assurance should examine the application as a connected system. A test may begin at the user-facing interface, continue through service logic, and verify the resulting database state. Check normal workflows as well as boundaries: empty or malformed inputs, repeated submissions, slow responses, and interrupted connections. For a service that processes updates, confirm that a retry does not create a duplicate operation and that a failed transaction does not leave partially changed data. These checks expose inconsistencies that a simple “request succeeded” result can miss.

Workload testing helps establish whether performance remains acceptable as demand changes. A load test measures behavior at an expected volume, while a stress test explores the point at which capacity or response quality degrades. Endurance testing can reveal resource leaks or gradual slowdown over a longer run. Recovery checks examine what happens after a process restart, a lost connection, or a temporarily unavailable dependency. Keep each test bounded and safe: use isolated environments where possible, define stop conditions, and avoid sending fault-injection traffic to systems that serve real users.

  • Functional consistency: Verify expected outputs, state changes, validation rules, and error handling for critical workflows.
  • Data integrity: Check transaction boundaries, duplicate prevention, backups, and restoration against defined recovery expectations.
  • Performance stability: Record response time, throughput, and resource use at representative and elevated workloads.
  • Dependency resilience: Test timeouts, retries, circuit-breaking behavior, and graceful handling of unavailable services.

Useful evidence includes test inputs, software build identifiers, environment configuration, timestamps, logs, and relevant resource measurements. A defect report should describe the observed behavior, expected behavior, reproduction steps, impact, and supporting evidence. This practical discipline turns an isolated failure into an actionable quality finding and makes later verification more reliable.

Quality assurance benefits of a balanced reliability program

A balanced reliability program improves more than the probability that a test passes. It helps teams understand where failures may occur, which controls reduce their impact, and whether changes have altered important behavior. Combining automated checks with focused exploratory testing can provide both repeatability and investigative depth. Automation is particularly effective for stable, frequently repeated scenarios; human review remains valuable when requirements are ambiguous, system interactions are complex, or results require contextual judgment.

  • Earlier defect discovery: Checks performed during development can expose failures before they become costly release issues.
  • More predictable releases: Consistent criteria give teams evidence for assessing change risk and readiness.
  • Faster diagnosis: Useful logs, traces, and reproducible scenarios narrow the search for root causes.
  • Stronger recovery planning: Recovery exercises reveal whether backup and restoration procedures meet agreed objectives.
  • Continuous improvement: Trends in incidents, test failures, and service measurements can guide future quality work.

These benefits depend on maintaining tests as software and operating conditions evolve. A test that once represented a real risk may become obsolete after an architectural change, while a newly introduced dependency may require additional coverage. Teams should review test relevance, remove redundant checks carefully, and track meaningful indicators such as failure rates, recovery time, and recurring defect categories. Measurements should support decisions rather than encourage teams to optimize a single number at the expense of user-visible behavior or data correctness.

Trustworthy evidence, security, and test data

Reliability testing must preserve the confidentiality, integrity, and availability of the systems and information involved. Use synthetic or appropriately masked data in non-production environments, restrict access to test artifacts, and avoid placing credentials or personal information in logs. When security controls affect reliability, verify that failures remain safe: authorization errors should not expose protected records, and rate limits should not silently corrupt transactions. Test environments should follow documented access and change procedures, particularly when exercises simulate outages or deliberately introduce faults.

Trustworthy results also require transparent limitations. A successful run describes behavior under the tested conditions; it does not guarantee that every workload, device, dependency, or failure scenario has been covered. Record the scope, assumptions, known gaps, and environmental differences alongside the findings. The label MAGICQA20261111L is only a temporary publication test label and should not be presented as evidence of independent assessment, compliance, or certification. Clear reporting helps readers and engineering teams distinguish measured results from expectations, estimates, and untested assumptions.

Choosing reliable checks for software quality assurance

Choose reliability checks according to the software’s critical workflows, architecture, and consequences of failure. A small internal utility may need focused functional, input-validation, and recovery tests, while a distributed service may also require workload, dependency, and long-duration checks. In either case, define observable acceptance criteria and make results reproducible. Review whether the test environment represents important production conditions, and identify gaps instead of treating them as proof of safety. This risk-based approach keeps quality assurance proportionate while ensuring that high-impact behaviors receive deliberate attention.

For each release, use the collected evidence to make a reasoned decision: which checks passed, which failed, what remains unknown, and what mitigations are available. Preserve the connection between requirements, tests, defects, fixes, and reruns so that reliability work can be reviewed over time. Software reliability is not a one-time certification exercise; it is an ongoing quality practice shaped by new code, dependencies, operating conditions, and observed incidents. Used in that context, MAGICQA20261111L remains simply a temporary editorial identifier, while sound test design and honest reporting provide the substance of assurance.

Transform Your Home with the Latest Trends in Blinds, Shades, and Shutters

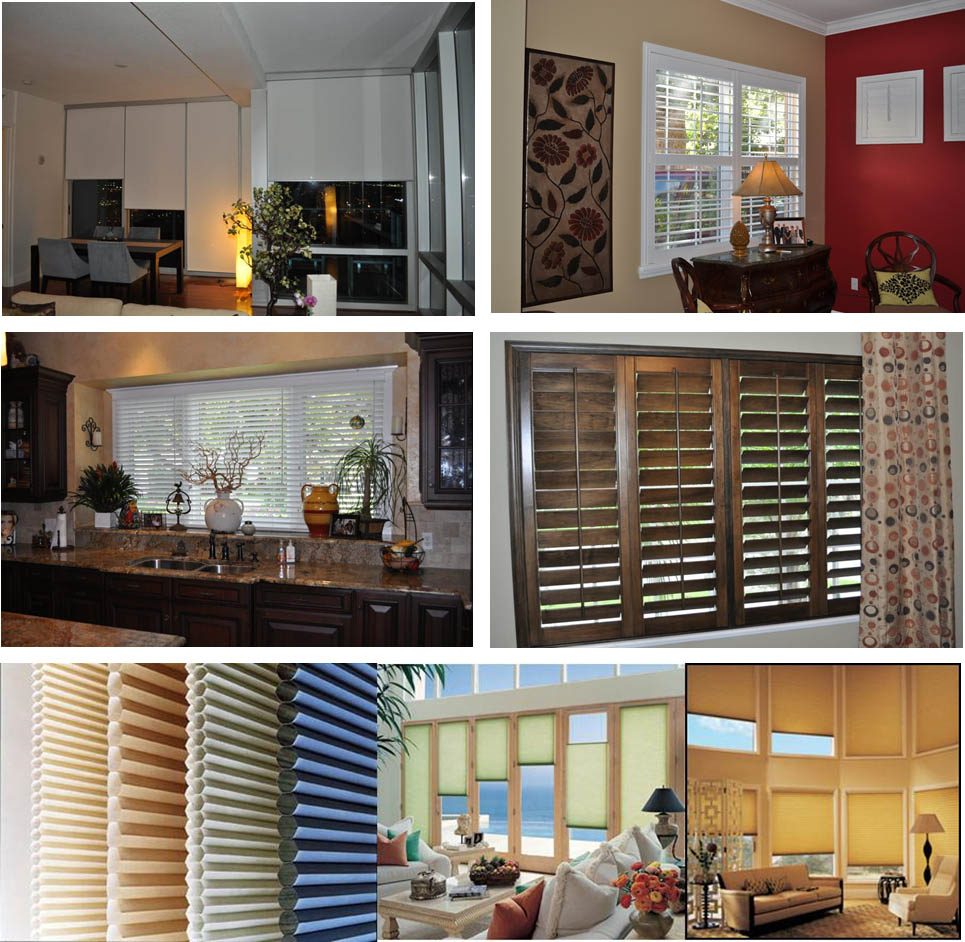
As the heart of your sanctuary, your home deserves to reflect your style and the latest trends in interior design. When it comes to transforming your living space, window treatments play a pivotal role. Blinds, shades, and shutters are not just functional; they also serve as stylish accents that can elevate the overall aesthetic of your home. Let’s explore the latest trends in these window coverings to help you infuse a touch of contemporary flair into your living spaces.

  1. Blinds: Sleek and Stylish

Blinds have undergone a modern makeover, with sleek and minimalist designs taking center stage. Opt for slimline aluminum or faux wood blinds in Orlando with narrow slats to achieve a chic and contemporary look. Neutral tones such as greys and charcoals are trending, providing a sophisticated backdrop for any interior style. Motorized blinds are also gaining popularity, offering convenience and a touch of luxury at your fingertips.

  • Shades: Textures and Patterns

Shades have embraced textures and patterns to add depth and visual interest to your windows. Look for cellular or Roman shades in Orlando with subtle textures like linen or woven fabrics. Bold patterns, such as geometric or floral prints, can make a statement and serve as a focal point in your room. Earthy tones and muted pastels are in vogue, creating a calming atmosphere while staying on-trend.

  • Shutters: Timeless Elegance with a Twist

Shutters, a timeless classic, have evolved to incorporate modern elements. Mix and match materials by combining wood with metal or opting for hybrid shutters that offer the best of both worlds. Plantation shutters in Orlando with wider louvers continue to be a popular choice, providing a sense of openness and allowing ample natural light. Consider experimenting with custom colors to make a bold statement that complements your interior palette.

  • Smart Solutions for Convenience

The integration of smart technology is a game-changer in the world of window treatments. Motorized blinds, shades, and shutters can be controlled effortlessly through your smartphone or smart home devices. This not only adds a touch of futuristic convenience but also allows you to manage natural light and privacy with precision. Smart solutions are an excellent investment for those looking to enhance both functionality and modernity in their homes.

Window treatments allow you to express your style while enjoying the benefits of innovative design. Whether you lean towards sleek blinds, textured shades, or timeless shutters, the key is to find a balance between aesthetics and functionality. Stay abreast of the latest trends with Gator Shutters to ensure your living spaces remain a reflection of contemporary elegance, providing comfort and style for years to come.

Dress Your Space with Unique and Trendy Roman Shade Styles

Roman shades have long been admired for their timeless elegance and versatility in window treatments. However, today’s market offers a plethora of unique and trendy Roman shade styles that can effortlessly elevate the aesthetic appeal of any space. In this blog post, Gator Shutters explores some of the latest Roman shade trends to help you dress your space with style and individuality.

  1. Classic Flat Roman Shades: Timeless Sophistication

Pros: – Clean and streamlined appearance. – Ideal for showcasing intricate patterns or vibrant colors. – Versatile, suiting both traditional and modern interiors.

Cons: – When raised, the folds stack up neatly, but they don’t provide the soft, cascading look of other styles.

  • Relaxed Roman Shades: Effortless Elegance with Soft Folds

Pros: – Cascading folds create a relaxed and informal look. – Perfect for spaces where a touch of softness is desired. – Offers a blend of sophistication and comfort.

Cons: – It may not be suitable for a more formal or structured aesthetic.

  • Balloon Roman Shades: Whimsical and Romantic

Pros: – Adds a touch of whimsy and romance to the space. – Creates a soft, billowing effect when raised. – Ideal for bedrooms, nurseries, or spaces with a vintage flair.

Cons: – The style may not suit every design scheme and could be too ornate for some tastes.

  • London Roman Shades: Tailored and Timeless

Pros: – Features a cascading swoop at the bottom when raised. – Offers a tailored and polished appearance. – Versatile and complements both traditional and contemporary interiors.

Cons: – The swoop can obstruct views when the shade is fully raised.

  • Austrian Roman Shades: Dramatic and Opulent

Pros: – Elaborate folds create a dramatic and opulent look. – Ideal for grand spaces or rooms with high ceilings. – Makes a bold design statement.

Cons: – Can be overpowering in smaller rooms or spaces with lower ceilings.

Dressing your space with unique and trendy Roman shade styles allows you to express your personality and elevate your interior design. Whether you opt for the timeless sophistication of classic flat Roman shades, the relaxed elegance of relaxed Roman shades, the whimsical charm of balloon Roman shades, the tailored look of London Roman shades, or the dramatic opulence of Austrian Roman shades, there’s a style to suit every taste and space.

Explore these trends, consider the pros and cons, and choose the Roman shade style that resonates with your design vision, creating a space that is both stylish and uniquely yours.

Curtains and Plantation Shutters – A Classic Match

In the realm of interior design, the pairing of curtains and plantation shutters has emerged as a timeless and elegant combination. This classic match elevates any space’s aesthetic appeal and offers a practical blend of functionality and style.

Harmony in Design:

The marriage of curtains and plantation shutters Orlando creates a harmonious balance between softness and structure. Curtains, with their flowing fabrics and various patterns, introduce a touch of warmth and grace. On the other hand, plantation shutters bring in a sense of order and sophistication with their clean lines and adjustable slats. Together, they form a visual symphony that complements diverse interior styles, from traditional to contemporary.

Versatility in Light Control:

One of the key advantages of this pairing is the versatility it offers in light control. Plantation shutters Orlando, with their adjustable louvers, allow for precise management of natural light. Curtains, with their varying thickness and fabrics, can be employed to further fine-tune the ambiance. Whether you desire a flood of sunlight or a cozy, dimmed atmosphere, this duo provides the flexibility needed to achieve the perfect balance.

Privacy Redefined:

Privacy is a crucial aspect of any living space and the combination of curtains and plantation shutters Orlando excels in providing just that. While shutters offer a practical solution for controlling the view from outside, curtains add an extra layer of seclusion. Drawing the curtains in the evening not only enhances privacy but also imparts a sense of intimacy to the room.

Aesthetic Elegance:

The aesthetic appeal of curtains and plantation shutters Orlando lies in their ability to enhance each other’s beauty. When paired with the clean lines of shutters, luxury drapes create a visual masterpiece. The curtains’ fabric softens the shutters’ appearance, adding texture and depth to the overall design. This dynamic interaction elevates the aesthetic elegance of any room, turning it into a haven of sophistication.

Energy Efficiency:

Beyond their visual impact, this classic match also contributes to energy efficiency. Plantation shutters Orlando, known for their insulation properties, help regulate the temperature in a room. Curtains, with their heavy fabrics, provide an additional layer of insulation. Together, they form a formidable barrier against external temperatures, keeping the interiors cooler in summer and warmer in winter, thus contributing to energy conservation.

Ease of Maintenance:

Practicality is another aspect where curtains and plantation shutters shine. Shutters are easy to clean and maintain, requiring minimal effort to keep them looking pristine. Curtains, with their removable and washable fabrics, also offer convenience in maintenance. This duo ensures that maintaining a stylish and tidy interior doesn’t become cumbersome.

Childproof your homes with these window coverings

Childproofing your home is important for ensuring the safety of your children. Many strangulation cases due to corded blinds and shades have been reported in the past in the U.S. Gator blinds shouters offer many options when selecting childproof options:

  • Cordless Blinds and Shades: As discussed above, cordless blinds and shades eliminate the risk of strangulation and make your homes safe for kids and pets alike.

Choosing cordless blinds and shades does not mean compromising on your taste and preferences. We bring cordless blinds and shades in various styles, designs, and textures.

  • Motorized Blinds and Shades: Consider motorized window treatments that can be operated using a remote control or a wall switch. With motorization, no cords are hanging down, reducing the risk of entanglement and making it safer for children.

Both cordless and motorized systems can be added to your existing window treatments, thus saving you money and effort. Seek professional help to learn more about this.

  • Top-Down/Bottom-Up Shades: These shades allow you to adjust the shade’s position from both the top and bottom. By opening the shades from the top, you can maintain privacy while still letting natural light into the room. This way, you can keep the lower portion of the window covered to prevent children from accessing it.
  • Retrofitting Corded Blinds: If you have existing corded blinds, you can retrofit them with cord safety devices. These devices can be installed to keep the cords taut and secured to the wall or window frame, reducing the risk of entanglement.

Remember, it’s crucial to regularly inspect and maintain your window blinds and shades to ensure they remain in good working condition and are safe for children. Additionally, please supervise your children around windows and teach them about window safety to further enhance their protection.

Many homeowners opt for installing window treatments on their own. However, we advise you to take professional help. Schedule a free in-home expert consultation where design experts come to your doorsteps. They’ll bring samples, and you can ask endless questions and get the best solutions at the best prices. They will take all the measurements and even provide installation services offering you peace of mind.

What are the best window treatments for your front door?

Choosing a window covering for your front door takes in many considerations. Security, durability and not to forget aesthetics should match the existing décor. Privacy is another major consideration to look for. So, what are those window coverings which offer all these features in today’s times.

Why choosing front door window covering requires much thought?

This is the first welcoming spot in your home is the front door. Apart from being functional, it should be welcoming and give a sneak peek to your style and taste. The material you choose for your front door coverings should be in your budget, meet your needs and purpose like offering privacy at night and light during the day etc.

Professional experts are the best to consult whenever you are in doubt or are overwhelmed with huge variety of options. Their hands on experience and keeping abreast with the latest trends, help you make an informed decision. You can schedule a free-in home consultation where experts would come to your home to understand your requirements and suggest the best window coverings.

Some of the most preferred window coverings for your front door are sliding doors, French doors. If you add cordless or motorized mechanism, it adds up a layer of security and safety especially when you have kids and pets around.

Some other options that work well for front door are –

Roman Shades – Roman shades add color and pattern to your front door making it more inviting. Choose motorized shades for comfort, convenience eliminating chances of cord getting in way of door.

Bamboo Shades or Woven Shades – They are an eco-friendly option and also being in a natural earthy element to the décor. They are made from natural materials like rattan , jute , reed and other grasses.

Cellular Shades – They are insulating window coverings allowing you to save energy and offering excellent light and privacy control. Choose from different opacities to choose the amount of light you want to allow in. To add comfort and convenience you can choose cordless control and create a clean look.

Which louver sizes for plantation shutters are the best for windows?

Installing high quality window coverings is seen as a valuable addition to homes. However, deciding on the perfect louver size can sometimes be confusing. Louvers are a set of slats that are fixed in a horizontal manner fixed in intervals for shutters. They are available in different sizes – 2 ½”, 3 ½”, or 4 ½” louvers. Let us start by asking a very basic but important question – Why does the louver size matter?

The louver size matters – it has a direct effect on the level of privacy, your view of the outside and the amount of light that will be coming in through the window. Moreover, the louver size also affects the overall look of the shutter and the room.

When to pick 2 ½” louver size?

  • When you have smaller windows

As a thumb rule, pick smaller louver size for smaller windows. If your window size is less than or 36” consider picking 2 ½” louvers.

  • When you have less window sill depth

There should be enough clearance to open and lower your louver. Otherwise they will be hitting the window pane. If you have less clearance space, opt for 2 ½” louver.

When to pick 3 ½” louver size?

  • If you want to go with the popular choice of homeowners

This size fits all medium and large windows and are a popular choice for homes as they offer a clean look.

  • If you are looking for larger panels

Wider panels fit perfect with 3 ½” and 4 ½” louvers. If you have a window that is about 72” wide and you opt for 2 ½” louver, you would require minimum three shutter panels to cover the window. This increases the cost also. Whereas if you opt for 3 ½” or 4 1/2 “, you would require only two shutter panels to cover the window. This also means that you can enjoy a wider unobstructed outside view.

When to pick 4 ½“ louver size?

  • Enjoy a less obstructed outside view

As we have discussed above already, wider louvers offer the best view when they are tilted to open. For medium to large windows in your homes, consider choosing 3 ½” or 4 ½” louver.

  • Allow more natural light to come in

As you enjoy a wider view with a 4 ½” louver, you will also get maximum light coming in and brighten up your space.